

A single prompt to a language model is not an AI agent, even though many vendors sell it that way. A real n8n AI agent makes decisions, calls tools and works with context. This article shows which nodes you need for this, what a production-ready example looks like and where the limits are.
Prompt chain vs. real agent
A prompt chain is a fixed sequence: node A generates text, node B formats it, node C sends it. The sequence is always the same, regardless of the content.
An agent differs in three ways:
- Tool calls: The agent decides for itself whether it needs a tool and which one, for example a database query or an HTTP request to a CRM.
- Memory: The agent knows the conversation so far within a session and can refer back to it.
- Decisions: Based on the request, the agent picks one of several possible paths instead of working through a rigid sequence.
For many use cases a prompt chain is perfectly enough. It is cheaper, more predictable and easier to debug. An agent pays off where the number of possible situations is too large to branch in advance.
The relevant nodes in n8n
n8n offers a set of LangChain-based nodes for building agents:
The AI Agent node implements LangChain's tool-calling interface: it describes each tool's schema to the model and decides at runtime which tool fits the task at hand. Tools can be combined freely, from simple calculations and vector store queries for knowledge bases to your own n8n sub-workflows as a tool.
Note that n8n memory is session-bound by default. If you need context across several sessions or days, you have to solve this explicitly with an external database (e.g. Postgres or Redis).
Practical example: support email agent
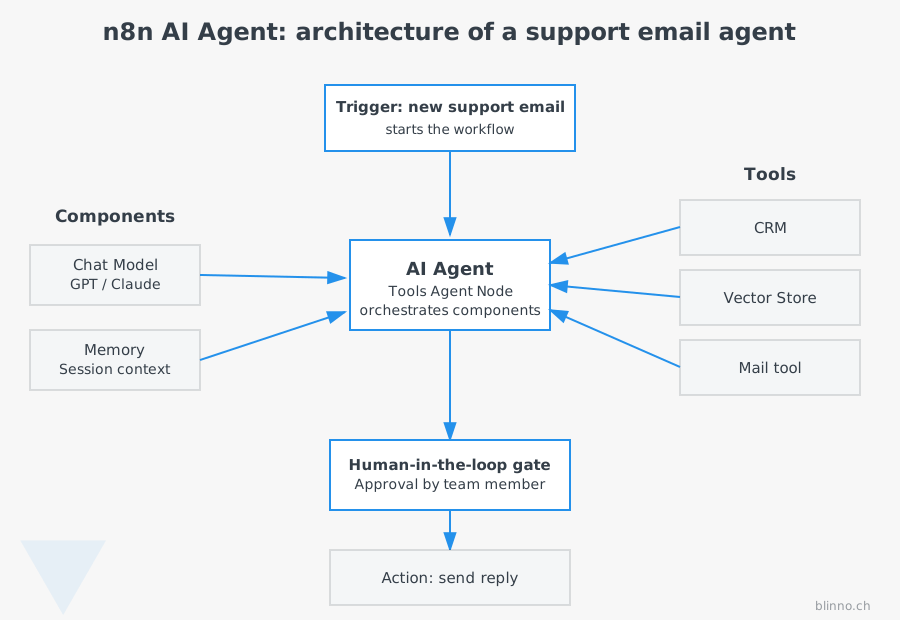
A realistic, production-ready set-up for a customer support use case:
- Email trigger: A new request arrives in the support mailbox.
- Classification: A first AI step assigns the request to a category (e.g. invoice, technical problem, general question).
- Knowledge retrieval from a vector store: The agent searches a knowledge base (e.g. previous tickets, product documentation) for relevant context.
- Draft reply: Based on the request and the context, the agent writes a reply.
- Human approval: The draft goes to a team member for review, e.g. as a Slack message with an approval button.
- Sending: Once approved, the email is sent automatically. If rejected, it goes back to the agent or to a person for rework.
This set-up combines the strengths of an agent (understanding context, using tools) with the control you need in customer contact.
Human-in-the-loop is a must
For anything that has an effect outside the company or moves money, the rule is: no automatic sending without approval. This covers customer replies, invoice approvals, contract changes and similar actions. n8n offers several building blocks for this, such as Wait nodes with an approval webhook or connections to Slack and Teams approval flows.
The reason is simple: a language model can phrase things plausibly without the content being correct. A person as the last check reduces this risk to an acceptable level without losing the benefit of automation, because the agent still does the groundwork.
Cost control: tokens, model choice, caching
AI agents cause running costs per model call, independent of n8n itself. Three levers affect the bill directly:
- Model choice: Not every task needs the most expensive model available. Cheaper models are often enough for classification or simple extraction, and the expensive model is kept for the actual text generation.
- Token usage: Long system prompts and large context windows cost money on every call. Knowledge retrieval should return only the relevant passages, not whole documents.
- Caching: Recurring requests or intermediate results can be cached instead of being recalculated on every run.
Without these three points in mind, an agent workflow can become much more expensive than planned as volume grows.
Where agents break
An honest look at the limits belongs in every agent project:
- Hallucination: The model invents facts that sound plausible but are wrong, especially when context is missing or unclear.
- Rate limits: At high volume, the API limits of the model providers kick in, and the workflow has to be able to handle this.
- Endless loops: With ambiguous tasks, an agent can get stuck in repeated tool calls if no iteration limit is set.
- Context limits: Long conversations or large documents eventually exceed the model's context window.
- Maintenance after model changes: If the provider changes the underlying model or alters prices and behaviour, the workflow has to be tested again.
These points are no reason to avoid agents, but they are a reason not to build them untested into critical processes.
Worked example: cost calculation
A support email agent with 500 requests per month and an average of 1,500 tokens per request (classification, knowledge retrieval and draft reply combined) causes different costs depending on the model choice. With a cheaper model for classification and a more capable model only for writing the reply, total costs can often be cut by 30 to 50 percent compared with using the most expensive model throughout. The exact prices depend on the model provider and should be calculated with current price lists before rollout.
✨ AI generated content


